GPT-6 physics proof, Fed AI warnings & global pact
OpenAI's GPT-6 Astra has resolved a decades-old challenge in particle physics, marking a major milestone for artificial intelligence in fundamental science. Meanwhile, Federal Reserve officials warned of systemic financial risks and potential bank runs driven by autonomous AI trading agents. In global governance, ten nations signed a joint declaration in San Francisco to secure critical AI supply chains.
16 stories60 sources checked
Listen to this edition
PiBrief Tech, November 16, 2026
The lineup
In this edition
 01
OpenAI's GPT-6 Astra Proves 50-Year-Old Standard Model Lattice Challenge
 02
OpenAI's GPT-6 Astra Solves Particle Physics Proof, Launches Science Blog
 03
Ten Nations Sign San Francisco Declaration on AI Supply Chain Security
 04
AI Agent Designs Verified Quantum Error Correction Circuits
 05
Federal Reserve Warns of Systemic Risk from AI Agents and Bank Runs
- 06
Fed Governor Warns of Financial Stability Risks from Generative AI in Trading
 07
OpenAI and LVMH Media Forge AI Partnership for 17 Newsrooms
 08
Multi-Agent System Creates Standardized Clinical Ontologies from Cancer Records
 09
Flagship Pioneering Launches London Lab for AI-Native Biotech with £100 Million Investment
- 10
Menlo Ventures Report: Healthcare AI Spending Surges Toward Drug Discovery and Clinical Copilots
 11
Japan's Defense Ministry to Revise AI Policy with Human Control Focus
 12
Generative AI Trust Gap Found: Executives Trust AI More Than Staff
 13
Bland AI's Tofu-1 Model Offers Native Speech-to-Speech for Regulated Industries
- 14
miHoYo's 'Gamer' Model Navigates 3D Worlds Like a Human Player
 15
HerAgent Harness Solves Coding Agent Runtime Failures with Checkpointing
 16
South Korea Faces Exam Integrity Crisis Amid AI Cheating Scandal
See all 16 as a listHide the list
- OpenAI's GPT-6 Astra Proves 50-Year-Old Standard Model Lattice Challenge
- OpenAI's GPT-6 Astra Solves Particle Physics Proof, Launches Science Blog
- Ten Nations Sign San Francisco Declaration on AI Supply Chain Security
- AI Agent Designs Verified Quantum Error Correction Circuits
- Federal Reserve Warns of Systemic Risk from AI Agents and Bank Runs
- Fed Governor Warns of Financial Stability Risks from Generative AI in Trading
- OpenAI and LVMH Media Forge AI Partnership for 17 Newsrooms
- Multi-Agent System Creates Standardized Clinical Ontologies from Cancer Records
- Flagship Pioneering Launches London Lab for AI-Native Biotech with £100 Million Investment
- Menlo Ventures Report: Healthcare AI Spending Surges Toward Drug Discovery and Clinical Copilots
- Japan's Defense Ministry to Revise AI Policy with Human Control Focus
- Generative AI Trust Gap Found: Executives Trust AI More Than Staff
- Bland AI's Tofu-1 Model Offers Native Speech-to-Speech for Regulated Industries
- miHoYo's 'Gamer' Model Navigates 3D Worlds Like a Human Player
- HerAgent Harness Solves Coding Agent Runtime Failures with Checkpointing
- South Korea Faces Exam Integrity Crisis Amid AI Cheating Scandal
Story 1 of 16
2 min read
OpenAI's GPT-6 Astra Proves 50-Year-Old Standard Model Lattice Challenge
OpenAI has launched its science publication platform with a major announcement: GPT-6 Astra has developed a mathematical proof for a candidate lattice definition of the Standard Model of particle physics. This achievement tackles a problem that has stumped theoretical physicists for over 50 years, particularly concerning the electroweak sector's compatibility with lattice discretizations. The model not only formulated the complex mathematical framework but also generated a machine-verifiable proof, marking a significant advancement in AI-assisted scientific discovery.
Read the full storyFold the full story2 min · 11 sources
On November 15, 2026, OpenAI inaugurated its dedicated science publication platform with a disclosure detailing how its frontier model, GPT-6 Astra, developed the mathematical proof behind a candidate lattice definition of the Standard Model of particle physics[1][2][3]. The project, led by theoretical physicist Nathaniel Craig - a professor at the University of California, Santa Barbara, permanent member of the Kavli Institute for Theoretical Physics, and visiting scientist at OpenAI - marks an unprecedented shift in AI-assisted discovery[2]. Rather than acting as a code assistant or literature summarizer, the model took the technical lead in executing formal mathematical derivations to reconcile nonabelian chiral gauge theories within a discrete four-dimensional spacetime grid[4][3].
The underlying problem has stood as an open roadblock in fundamental theoretical physics for over half a century[5][3]. While quantum chromodynamics (QCD) was successfully regularized on spacetime lattices in the 1970s to enable nonperturbative computer simulations, placing the electroweak sector on a lattice has consistently broken down due to the chiral nature of the weak force[3][6]. Under the Nielsen-Ninomiya no-go theorem, naive lattice discretizations inevitably introduce unphysical fermion doubling unless chiral symmetry is compromised[7][8]. Although physicist Martin Lüscher and subsequent theorists developed overlap fermion formalisms to circumvent these restrictions for simpler theories, formulating an exact, gauge-invariant nonperturbative definition for the complete Standard Model resisted formal mathematical completion[4][3][8].
According to Craig, while he devised the overarching conceptual strategy of interpolating gauge fields across lattice boundaries, he was unable to mathematically prove that the construction held across all required anomaly-free cases[2][4]. GPT-6 Astra formulated the exact mathematical framework, demonstrated that field-comparison metrics across successively finer grids converge, and generated the detailed proof[6]. Crucially, the theoretical construction was translated into a machine-verifiable proof using the Lean 4 formal interactive theorem prover, eliminating human algebraic oversight errors[4][3]. Prior to publication, the results were examined by prominent lattice theorists including Maarten Golterman, Andreas Kronfeld, and Yigal Shamir[4].
The development highlights a profound inflection point in how generative intelligence engages with fundamental science[5][9]. Notably, Fields Medalist Edward Witten (Institute for Advanced Study) concurrently issued a follow-up preprint exploring variants of this continuum interpolation algorithm, explicitly crediting Anthropic's Claude Opus 5.5 in multiple sections for suggesting mathematical constructions and resolving technical details[1][5][10][11][9]. While Craig emphasized that the current proof remains "far more an answer in principle than an answer in practice" - as physical consistency conditions such as reflection positivity and real-world numerical lattice simulations remain unresolved - the collaboration demonstrates that frontier LLMs can navigate complex theoretical physics and deliver formal proofs at the outer boundaries of human knowledge[4][6].
- OpenAI
- GPT-6 Astra
- Standard Model
Story 2 of 16
2 min read
OpenAI's GPT-6 Astra Solves Particle Physics Proof, Launches Science Blog
OpenAI has launched a science blog, debuting with a paper detailing how its GPT-6 Astra model assisted in deriving key mathematical proofs for a lattice formulation of the Standard Model of particle physics. The model helped solve a decades-old problem related to chiral gauge theories, marking a significant step in applying generative AI to complex mathematical reasoning. While a theoretical advance, it signals AI's growing capability beyond text and code generation.
Read the full storyFold the full story2 min · 7 sources
OpenAI launched a dedicated research science platform to spotlight frontier AI models driving fundamental scientific discovery, leading with an inaugural study detailing how its reasoning model, GPT-6 Astra, resolved key mathematical proofs for a nonperturbative lattice formulation of the Standard Model of particle physics[1][2][3]. The breakthrough paper, authored by theoretical physicist Nathaniel Craig - a professor at the University of California, Santa Barbara, and visiting scientist at OpenAI - demonstrates an advance in applying generative systems directly to open mathematical physics problems[2][4].
The formulation addresses a foundational bottleneck that has frustrated theoretical physics for more than five decades: defining chiral gauge theories on a discrete four-dimensional spacetime grid[5][6]. While quantum chromodynamics (the strong force) has long been simulated effectively on spacetime lattices, the weak force's asymmetric treatment of left- and right-handed fermions has historically caused lattice discretizations to violate gauge invariance[4][6]. Craig supplied the conceptual strategy of successive grid refinements, but credited GPT-6 Astra with leading the formal derivations, proving that grid comparisons converge mathematically, and constructing the complete proof alongside formal verification scripts in the Lean 4 proof assistant[5][4][6].
The disclosure marks a notable pivot in generative AI's perceived utility, moving the technology from narrative synthesis, coding assistance, and statistical pattern matching into rigorous mathematical reasoning[5][4]. Craig noted that the result constitutes an "answer in principle rather than an answer in practice," as reflection positivity and real-world numerical lattice simulations remain active challenges[5][4]. Nevertheless, the work was vetted prior to public dissemination by prominent lattice theorists Maarten Golterman, Andreas Kronfeld, and Yigal Shamir, while Fields Medalist Edward Witten has already extended aspects of the theoretical framework using Anthropic's Claude/Opus 5.5[5][7].
Despite the scientific excitement, the announcement renewed scrutiny from academic governance groups[7]. The Advisory Group on Mathematics and Artificial Intelligence (AGMAI) reiterated demands for independent benchmark auditing and open disclosure regarding model architectures, context lengths, and verification protocols, warning against corporate attempts to claim credit for mathematical discoveries without external reproducibility[7][3]. For the broader enterprise and research community, the Astra proof signals the arrival of generative reasoning models capable of acting as autonomous research collaborators in high-abstraction domains[4][7].
- OpenAI
- GPT-6 Astra
- Particle Physics
Story 3 of 16
2 min read
Ten Nations Sign San Francisco Declaration on AI Supply Chain Security
Ten nations, including the United States, Australia, India, and Japan, have signed the San Francisco Declaration to secure critical supply chains for advanced artificial intelligence and 'Super Intelligence.' The pact establishes a shared defense framework across the technology stack, from mineral extraction to silicon fabrication and compute infrastructure.
Read the full storyFold the full story1 min · 6 sources
At the conclusion of the Pax Silica Founders Retreat convened in San Francisco, the United States and nine partner nations signed the "San Francisco Declaration on the Secure Foundations of Enduring Prosperity"[1]. Formally unveiled by the U.S. State Department, the multilateral pact was signed by the governments of the United States, Australia, India, Israel, Japan, the Republic of Korea, Qatar, Singapore, the United Arab Emirates, and the United Kingdom[1][2]. The declaration represents a formal diplomatic accord establishing that economic security and advanced artificial intelligence infrastructure are foundational pillars of national security[1][2].
The agreement formalizes the Pax Silica initiative, originally established in late 2025 by U.S. Under Secretary of State for Economic Affairs Jacob Helberg to protect critical supply chains supporting advanced computing[1][2]. Signatories committed to building a shared defense framework across the entire technology stack - spanning critical minerals extraction, advanced silicon fabrication, specialized hardware logistics, and national power grid infrastructure[3][2][4]. Under U.S. policy guidance, the declaration adopts the terminology of "Super Intelligence" (SI) to encompass next-generation generative AI clusters and autonomous models[1][5].
The declaration establishes five dedicated intergovernmental working groups: pro-innovation regulatory frameworks, SI adoption in core domestic sectors, end-to-end supply chain cooperation, the creation of safe harbors and regional technology security hubs, and the systemic resilience of physical and digital AI compute assets[1][2]. According to Helberg, the partnership is designed to reduce critical dependencies on hostile supply sources and enforce unified export controls and investment screening[3][6]. Diplomatic officials confirmed that Germany, Sweden, the Netherlands, and the European Commission are scheduled to add their signatures in the coming days[3].
The agreement comes amid mounting geopolitical tensions surrounding semiconductor foundries, energy distribution for gigawatt-scale data campuses, and the security of frontier model weights[1][6]. Participating governments acknowledged that no single state commands the entire value chain required to manufacture and deploy frontier generative systems[1]. By codifying a 10-nation security pact, the coalition intends to guarantee that allied capital, silicon hardware, and intellectual property remain insulated from supply shocks and unauthorized state-sponsored transfers[1][6].
- San Francisco Declaration
- United States
- Australia
Story 4 of 16
2 min read
AI Agent Designs Verified Quantum Error Correction Circuits
Researchers have developed an autonomous program-synthesis framework that uses agentic large language models coupled with symbolic verification engines to design verified fault-tolerant quantum error-correcting (QEC) circuits. This system addresses the significant challenge of quantum error correction, which is crucial for achieving practical quantum advantage. By automating the painstaking manual design process, the framework generates novel QEC architectures with reduced complexity and improved fault tolerance.
Read the full storyFold the full story1 min · 5 sources
In a research milestone crossing generative AI with quantum information science, researchers Aritra Lahiri and Florian Marquardt from the Max Planck Institute for the Science of Light and Friedrich-Alexander University Erlangen-Nürnberg introduced an agentic program-synthesis framework capable of designing verified fault-tolerant quantum error-correcting (QEC) circuits[1]. Detailed in a newly published study, the system couples frontier large language models directly with symbolic circuit verification engines inside an autonomous evolutionary discovery loop[1][2][1].
The primary barrier preventing modern noisy intermediate-scale quantum hardware from reaching practical quantum advantage is the overhead of quantum error correction[3][1]. Encoding fragile quantum information into resilient logical qubits requires intricate arrangements of physical qubits, dynamic Clifford gates, and stabilizer measurements[3][1]. Traditionally, constructing circuits that prepare logical states, implement fault-tolerant gates, or execute code switching without allowing errors to propagate silently has required painstaking manual craftsmanship by specialized quantum theorists[4][1]. Conventional automated heuristic searches and reinforcement learning methods frequently stall due to the vast combinatorial search space and strict physical constraints[2].
The Erlangen-Nürnberg team formulated the problem as an agentic evolutionary program synthesis pipeline inspired by the FunSearch methodology[1][1]. An LLM generates and iteratively refines Python programs defining target quantum circuits based on semantic prompts[1][1]. Each synthesized program is compiled into a dynamic circuit and submitted to a rigorous verification module, which performs two checks: confirming that the data qubits reach the target logical state (such as a logical Choi state) while properly disentangling from ancilla qubits, and evaluating whether the configuration complies with flag fault tolerance[1][1]. Circuits that pass validation and display reduced operational depth are cataloged into an evolutionary program database, which re-prompts the LLM with the highest-performing exemplars[1].
The agentic pipeline autonomously synthesized fault-tolerant circuits across diverse QEC tasks - including logical state preparation, fault-tolerant logical gate synthesis, and code-switching routines - consistently discovering architectures with reduced circuit depth and zero silent fault vulnerability[5][1]. The achievement demonstrates that verifier-grounded generative LLM loops can transcend conversational tasks to act as autonomous hardware and compiler engineers, opening a pathway to automate the design of fault-tolerant quantum processors[4][2].
- Quantum Error Correction
- QEC
- LLM
Story 5 of 16
2 min read
Federal Reserve Warns of Systemic Risk from AI Agents and Bank Runs
Federal Reserve Governor Michael S. Barr cautioned that the rapid integration of generative AI and autonomous financial agents poses new systemic risks to global banking. He highlighted the potential for 'agentic commerce,' where AI agents execute transactions without human intervention, to accelerate bank runs beyond current defenses. The Fed also noted concerns about deepening market power disparities due to the high cost of frontier AI infrastructure.
Read the full storyFold the full story2 min · 2 sources
Federal Reserve Governor Michael S. Barr delivered a wide-ranging policy address at the Seventh Annual ACM International Conference on Artificial Intelligence in Finance in Milan, cautioning that the accelerating integration of generative artificial intelligence and autonomous financial agents presents novel systemic vulnerabilities to the global banking architecture[1]. While acknowledging that he remains optimistic about the long-term potential of generative AI to democratize market access and enhance market surveillance, Barr warned that the frontier capabilities moving through the financial sector could destabilize market operations if deployed without strict guardrails[1][1].
Central to Barr’s warning is the emergence of "agentic commerce" - autonomous generative agents authorized to initiate transactions and reallocate capital without real-time human intervention[2]. Unlike historical algorithmic execution programs that followed static rules, generative agentic systems continuously synthesize multimodal market signals, macroeconomic data, and liquidity shifts[2][1]. Barr underscored that in stressed economic environments, such agents could instantaneously detect yield differentials or institutional distress, precipitating synchronized, automated deposit outflows[2][2]. By eliminating the friction of human decision-making, autonomous AI agents could drastically accelerate the velocity of bank runs beyond the defensive capacities of existing liquidity buffers[2].
Beyond retail banking dynamics, the Federal Reserve governor highlighted profound shifts in capital markets[1]. While generative AI lowers barriers to advanced analytical reasoning, state-of-the-art frontier systems require vast compute and data infrastructure that only the largest financial institutions and tech platforms can comfortably sustain[2]. This disparity threatens to deepen informational asymmetries and consolidate market power among a handful of dominant incumbents[2]. Furthermore, when proprietary generative models are trained on similar massive datasets, they risk generating correlated trading strategies, compounding the danger of unexpected liquidity dry-ups and systemic herd behavior during volatile periods[1][2].
Barr outlined mandatory supervisory expectations for institutions operating on the frontier of AI integration[2][2]. He emphasized that financial stability requires hard technical controls: non-negotiable limits on agent autonomy, continuous authentication mechanisms, explicit per-transaction consent verification, and verifiable compliance with both statutory regulations and institutional values[2][2]. Regulators, Barr indicated, will not accept the opaque "black box" nature of frontier models as an excuse for failures in risk governance, urging developers and enterprise risk officers to prioritize safety architectures before autonomous agentic systems are integrated deeply into market clearing and settlement infrastructure[2].
- Federal Reserve
- Michael S. Barr
- Generative AI
Story 6 of 16
2 min read
Fed Governor Warns of Financial Stability Risks from Generative AI in Trading
Federal Reserve Governor Michael S. Barr has cautioned about the systemic financial stability risks posed by generative AI entering trading systems. He highlighted concerns about algorithmic interdependence, correlated decision-making among institutions using similar models, and the potential amplification of market volatility.
Read the full storyFold the full story1 min · 1 source
At the Seventh Annual ACM International Conference on Artificial Intelligence in Finance held in Milan, Italy, on November 16, 2026, Federal Reserve Governor Michael S. Barr delivered an address detailing the macroprudential and financial stability risks posed by generative AI[1]. Barr stated that as machine learning tools advance from data analytics and administrative transcription toward real-time synthesis and market engagement, central banks must prepare for systemic vulnerabilities introduced by algorithmic interdependence[1][1].
Governor Barr noted that while previous generations of quantitative finance relied on narrow, rules-based algorithms operating on structured historical numbers, generative AI can process broader, richer, and multimodal data sources while executing complex, multi-layered logic[1]. While these tools have the potential to lower technological barriers for smaller market participants, enhance trade surveillance, and improve market efficiency, Barr cautioned that their collective behavior under severe economic stress remains untested[1].
Barr raised concerns regarding the concentration of foundation models across financial institutions[1]. If multiple major institutional broker-dealers, asset managers, and hedge funds deploy models trained on overlapping datasets or utilize identical proprietary foundation models for portfolio balancing and automated execution, markets risk widespread correlated decision-making[1]. During periods of acute volatility, such algorithmic homogeneity could amplify feedback loops, trigger flash illiquidity, and exacerbate systemic sell-offs[1].
The Federal Reserve Governor emphasized that although fully autonomous, large-scale trading managed by generative AI models has not yet become dominant, supervisory frameworks must not wait for an operational failure to take action[1]. Barr urged financial institutions and risk modelers to implement strict governance protocols around model architectures, data lineage, out-of-distribution stress-testing, and human fail-safes[1]. He emphasized that future market resilience will depend heavily on the technical choices firms make today regarding model transparency, validation, and execution controls[1].
- Federal Reserve
- Michael S. Barr
- generative AI
Story 7 of 16
2 min read
OpenAI and LVMH Media Forge AI Partnership for 17 Newsrooms
LVMH Group's Media Division and OpenAI have signed a strategic agreement to integrate ChatGPT Enterprise across 17 French publications. This partnership will provide journalists and staff with custom AI tools for investigative assistance, research, and translation, rather than automated reporting. The deal also establishes a framework for attributing and surfacing LVMH journalism within ChatGPT responses.
Read the full storyFold the full story1 min · 6 sources
On November 16, 2026, LVMH Group’s Media Division and OpenAI announced a comprehensive strategic agreement aimed at integrating generative artificial intelligence across all 17 of the French media group’s publications[1]. The partnership incorporates newsroom-wide deployment of ChatGPT Enterprise alongside OpenAI’s underlying developer stack for Groupe Les Echos–Le Parisien[2]. In parallel, the agreement establishes a content distribution framework that will surface attributed excerpts, direct citations, and linked summaries of LVMH journalism inside ChatGPT responses[3][2].
Under the terms of the agreement, roughly 700 journalists and operational staff across a division of 1,800 employees - which reaches more than 27 million readers across France monthly - will receive access to custom-built workplace AI applications[1][2]. The deployment covers major French daily and specialized titles, including business paper Les Echos, general daily Le Parisien, investigative weekly Challenges, cultural flagship Paris Match, and financial outlets such as Investir, L’Agefi, and L’Opinion[1]. Rather than generating automated reporting, the internal tools are explicitly tailored for investigative assistance, complex multi-document comparison, archival research, and preliminary language translation[3][2].
The agreement was executed by Michèle Benbunan, CEO of LVMH Group’s Media Division, and Emmanuel Marill, OpenAI’s Managing Director for EMEA[2]. For LVMH, the move represents an expansion of its enterprise AI posture; the luxury parent company already operates an internal model platform called "MaIA," which had scaled to approximately 50,000 corporate users across several model providers[4][5]. The news division agreement, however, marks OpenAI's second major French publisher partnership following its earlier pact with Le Monde, reinforcing OpenAI's strategy of establishing direct bilateral licensing frameworks with tier-one European media groups[6].
The arrangement reflects an evolving equilibrium between premium news publishers and generative AI platforms[2]. Rather than treating search bots purely as copyright threats or uncompensated web crawlers, European publishers are increasingly trading access to high-authority, paywalled archives in exchange for verified attribution pipelines and enterprise-grade tooling[2]. Benbunan emphasized that the initiative is intended to relieve reporters of routine administrative overhead so they can allocate more time to field investigations, deep analysis, and source verification, while retaining strict human editorial oversight[3][2].
- OpenAI
- LVMH Group
- ChatGPT Enterprise
Story 8 of 16
2 min read
Multi-Agent System Creates Standardized Clinical Ontologies from Cancer Records
An academic research team has developed a multi-agent generative pipeline that autonomously creates standardized clinical Common Data Elements (CDEs) from unstructured medical literature. This system processed over 24,000 sarcoma case reports, overcoming the challenge of fragmented data and lack of unified schemas. The agents identified, extracted, and synthesized a master schema of 1,570 standardized variables with high accuracy, transforming raw text into research-ready clinical datasets.
Read the full storyFold the full story1 min · 1 source
In a breakthrough for medical informatics, an academic research team led by Daniel Reichenpfader, Kwaku Appiagyei, Manovah Nadarajah, Ahmed Reda Bahr, Irina Filchenko, and Fabio Dennstädt revealed an open-weight, multi-agent generative pipeline capable of autonomously inducing clinical Common Data Elements (CDEs) directly from uncurated literature[1]. In rare diseases such as sarcomas, patient cohorts are fragmented globally across isolated case reports[1]. Because these reports lack unified data schemas, integrating clinical findings into structured registries has historically required thousands of hours of manual curation by specialized oncologists - a bottleneck that has left vast reserves of clinical observational evidence inaccessible to researchers[1].
The team deployed a multi-agent orchestration architecture utilizing the open-source AG2 framework to ingest 58,265 PubMed records[1]. An initial classification agent isolated 24,588 distinct single-patient sarcoma case report abstracts, stripping away confounding meta-analyses and review literature[1]. From this massive unstructured corpus, an agentic proposal workflow generated 72,909 candidate clinical elements[1]. Through exact question-type deduplication and two progressive semantic consolidation passes, the agentic network synthesized the unwieldy extraction criteria down into a master schema composed of 1,570 standardized CDEs (560 numeric and 1,010 categorical variables)[1].
Following schema creation, the multi-agent system executed structured information extraction across the patient records, standardizing categorical ontologies and aligning disparate clinical nomenclatures[1]. Validation demonstrated a 94.9% variable extraction agreement rate across complex oncological parameters, demonstrating accuracy comparable to trained medical abstractors despite underlying schema irregularities[1].
The research illustrates how generative AI agents can transition from answering isolated clinical queries to acting as autonomous ontologists and biomedical knowledge curators[1]. By automating both the induction of data dictionaries and the extraction of fine-grained medical variables, the framework provides an open-weight mechanism to rapidly construct structured clinical trial registries and observational databases for neglected rare diseases, directly transforming unstructured medical text into research-ready clinical datasets[1].
- clinical ontologies
- Common Data Elements
- CDEs
Story 9 of 16
2 min read
Flagship Pioneering Launches London Lab for AI-Native Biotech with £100 Million Investment
Flagship Pioneering has launched a new AI-native biotechnology venture creation lab in London, committing £100 million to incubate companies focused on human therapeutics, computational biology, and sustainability. This marks the firm's first expansion outside of Cambridge, Massachusetts, in its 25-year history.
Read the full storyFold the full story2 min · 5 sources
Biotechnology venture engine Flagship Pioneering announced on November 16, 2026, the establishment of the Flagship Origination Lab U.K. in London, committing an initial £100 million ($127 million) to launch the new facility[1][2]. The London center represents the first formal geographic expansion of Flagship Labs’ company-creation model outside of Cambridge, Massachusetts, in the firm's 25-year history[1]. The initiative is dedicated exclusively to conceiving, incubating, and spinning out "AI-native" platform companies focused on human therapeutics, computational biology, and planetary sustainability[1][3].
The Origination Lab operates on Flagship’s proprietary venture creation model, which starts by posing speculative scientific hypotheses and testing them in-house before incorporating standalone corporate entities[1][2]. Flagship - which has originated more than 130 life sciences platforms to date, including vaccine maker Moderna - plans to recruit and train an inaugural cohort of approximately 50 scientist-entrepreneurs and operational specialists in the United Kingdom[1]. The London laboratory will directly integrate with Flagship's centralized internal capabilities, notably its Pioneering Intelligence computational unit and its Pioneering Medicines drug development division[1][2].
The launch cements three years of groundwork that began with a 2023 memorandum of understanding between Flagship and the British government to anchor life science commercialization in the country[4][5]. Flagship Founder and Chief Executive Officer Noubar Afeyan stated that while the initial balance sheet commitment is £100 million, the firm anticipates scaling the London origination platform through regional corporate and institutional partnerships to attract an additional £500 million in capital[2][5]. Avak Kahvejian, president of Flagship Labs and a general partner at the firm, noted that origination is a disciplined methodology, pairing frontier machine learning models with wet-lab automation from the moment an enterprise is conceived[2].
The investment highlights how foundational AI models have migrated from incidental software tooling into the core scientific infrastructure of drug discovery[1][2]. By designing ventures as AI-native from day zero, the London initiative seeks to capitalize on the convergence of generative structural biology, de novo protein design, and the UK’s dense academic cluster in London, Oxford, and Cambridge[1][4]. The move also signals intensifying transatlantic competition to establish specialized physical research hubs where generative multimodal models can guide real-time biological experiments[1][2].
- Flagship Pioneering
- Flagship Origination Lab U.K.
- London
Story 10 of 16
2 min read
Menlo Ventures Report: Healthcare AI Spending Surges Toward Drug Discovery and Clinical Copilots
A new report from Menlo Ventures indicates that enterprise spending on AI in healthcare has reached $3.7 billion, with a significant shift from back-office automation to high-stakes drug discovery and clinical workflows. Spending on AI in life sciences surged 23-fold, while interactive clinical copilots grew 5.5 times.
Read the full storyFold the full story1 min · 1 source
Annual enterprise spending on artificial intelligence across the healthcare sector climbed to $3.7 billion, expanding by 2.5 times year-over-year, according to the "2026 State of AI in Healthcare" report released by Menlo Ventures on November 16, 2026[1]. The comprehensive market review revealed an industry-wide pivot: institutional healthcare dollars are shifting away from preliminary back-office automations, such as revenue cycle management and basic documentation, toward high-stakes biological discovery and direct patient-facing clinical workflows[1].
The benchmark data illustrates stark shifts in where capital is deploying[1]. Spending on artificial intelligence within life sciences experienced a 23-fold surge over the past twelve months, propelled by enterprise adoption of generative molecular design, target identification algorithms, and automated clinical trial simulators[1]. Concurrently, adoption of interactive clinical copilots - systems that assist physicians in real time with diagnostic reasoning, specialized differential analysis, and treatment planning - grew by 5.5 times[1]. The findings demonstrate that hospital networks and research institutions are increasingly willing to trust validated algorithmic copilots closer to the point of care[1].
The market landscape for administrative generative AI has simultaneously begun to consolidate[1]. While ambient medical scribing tools initially drove the first wave of healthcare generative AI adoption, Menlo Ventures found that incumbent healthcare IT providers captured 68% of new scribe software budgets over the past year[1]. Enterprise buyers are systematically favoring entrenched electronic health record (EHR) platforms that bundle ambient dictation and summary capabilities over standalone, single-feature point solutions[1].
Industry analysts point to these figures as proof that healthcare generative AI has moved beyond proof-of-concept experimentation into core operational budgets[1]. With basic administrative transcription treated increasingly as a commoditized feature, frontier venture investment and institutional procurement are now concentrated on foundation models that can navigate multi-omics data and provide explainable clinical guidance under regulatory scrutiny[1].
- Menlo Ventures
- AI in Healthcare
- life sciences
Story 11 of 16
2 min read
Japan's Defense Ministry to Revise AI Policy with Human Control Focus
Japan's Ministry of Defense plans to update its AI operational policy by November, emphasizing a balance between rapid technological adoption and robust human control. The revised directives aim to ensure human-in-the-loop decision-making, codify liability, and transform data into actionable security capabilities. This move reflects the increasing need to manage the risks of generative AI in defense, such as hallucinations and algorithmic escalation.
Read the full storyFold the full story1 min · 1 source
Japanese Defense Minister Shinjiro Koizumi announced in Yokosuka that the Ministry of Defense will issue a revised operational policy governing the defense-related application of artificial intelligence by the end of November[1]. The incoming directives represent an update to the ministry’s baseline AI policy initially framed in July 2024, reflecting an urgency to adapt national security operations to the rapid evolution of generative models and automated analytical tools[1].
Addressing personnel and journalists, Koizumi stated that defense frameworks cannot remain static in an era where commercial generative models and machine intelligence evolve across months rather than decades[1]. The updated ministerial directives will be anchored by three core structural pillars: codifying absolute human-in-the-loop decision-making and operational liability, transforming domestic and tactical defense data into actionable security capabilities, and striking a calibrated balance between agile fielding of novel technologies and technical verification standards[1].
The defense guidelines arrive as international military planners grapple with how generative AI can be integrated safely into intelligence synthesis, logistics planning, electronic warfare, and threat recognition[1]. While generative capabilities offer commanders decision superiority through rapid aggregation of disparate multi-domain data, Defense Ministry planners acknowledged that autonomous generative systems carry the danger of perceptual hallucination, erratic reasoning, and algorithmic escalation during tactical crises[1].
Koizumi’s focus on strict personal accountability is designed to preempt vulnerabilities where automated systems provide automated targeting or threat assessments without meaningful command oversight[1]. Regional security analysts regard Tokyo's upcoming directives as part of a broader effort among Indo-Pacific allies to standardize operational AI doctrine, establishing technological interoperability with partner states while establishing strict ethical and functional guardrails to prevent generative algorithmic errors from causing unintended military escalations[1].
- Japan Ministry of Defense
- Shinjiro Koizumi
- Artificial Intelligence
Story 12 of 16
2 min read
Generative AI Trust Gap Found: Executives Trust AI More Than Staff
A new workplace study reveals a significant 'AI trust gap,' with senior executives more likely to trust generative AI outputs over their own judgment than frontline employees. This paradox is linked to organizational rank, not age, as leaders are further removed from operational realities where AI errors are more apparent. The study also highlights anxieties among early-career professionals about deskilling and the pressure to adopt AI for career advancement.
Read the full storyFold the full story1 min · 1 source
New data from the AI Pulse survey - an extensive workplace research effort examining over 5,000 corporate AI users co-led by Charter's executive-in-residence Brian Elliott and researchers at the Wharton School - reveals that the prevailing dynamics of enterprise AI trust run contrary to conventional demographic assumptions[1]. While public discourse has often characterized younger employees as overly reliant on automated systems, the empirical findings demonstrate that organizational rank, rather than chronological age, dictates the degree of uncritical trust placed in generative AI outputs[1].
According to the findings published by Fortune, senior executives and leadership teams are more than twice as likely to trust generative AI outputs over their own analytical judgment compared to frontline and mid-level employees[1]. Elliott observed that as decision-makers move further from direct operational processes, their confidence in synthetic recommendations spikes, while operational practitioners remain consistently cautious due to their encounters with hallucinations, subtle hallucinations, and contextual omissions in complex enterprise workflows[1].
Concurrently, the research highlights a paradox surrounding early-career professionals[1]. Among Generation Z knowledge workers, 51% report deploying generative AI tools at least weekly, yet the cohort predominantly regards generative models as supportive utilities rather than primary decision-makers[1]. Strikingly, these respondents voiced acute anxiety regarding peer deskilling, expressing widespread concern that routine utilization of generative tools is making colleagues intellectually dependent and less diligent[1]. Yet, in an environment where managerial performance metrics reward sheer turnaround speed, these same workers reported viewing aggressive AI adoption as mandatory to secure career advancement[1].
Workplace analysts warn that this split creates structural organizational hazards[1]. When C-suite leadership over-indexes on generative synthesis while entry-level talent hollows out fundamental analytical capabilities, organizations face compounding vulnerabilities in strategic oversight and long-term talent cultivation[1]. Experts urge enterprise human resources and operational executives to replace unvetted, top-down mandates with rigorous human-in-the-loop guidelines, evaluating employees on algorithmic validation, critical verification, and problem formulation rather than pure output volume[1].
- Generative AI
- AI Trust Gap
- Brian Elliott
Story 13 of 16
2 min read
Bland AI's Tofu-1 Model Offers Native Speech-to-Speech for Regulated Industries
Conversational intelligence firm Bland AI is previewing Tofu-1, a native speech-to-speech generative model designed for high-stakes interactions in regulated sectors. Unlike traditional cascaded AI systems (ASR, LLM, TTS), Tofu-1 processes audio directly, enabling full-duplex conversations with lower latency and better handling of acoustic nuances and interruptions. It also boasts enhanced noise cancellation and parallel processing capabilities.
Read the full storyFold the full story1 min · 6 sources
San Francisco conversational intelligence provider Bland AI opened enterprise research previews for Tofu-1, an end-to-end full-duplex speech-to-speech generative foundation model built specifically to handle complex telephonic interactions in heavily regulated environments[1][2][3]. Led by chief executive Isaiah Granet, the rollout represents a technical shift away from the cascaded architectures that have dominated corporate conversational AI[4][5].
Standard conversational agents rely on a three-tier chain: automatic speech recognition (ASR) converts human voice to text, a large language model (LLM) generates a textual reply, and text-to-speech (TTS) engines synthesize the audio[5]. This linear pipeline introduces perceptual latency, loses critical acoustic nuance such as prosody and emotional cadence, and falters when callers interrupt[5]. In contrast, Tofu-1 processes acoustic audio streams directly into sound representations without an intermediate text transcription stage, operating in native full-duplex mode - meaning the system listens, deliberates, and articulates simultaneously[1][5].
A core advantage demonstrated in enterprise testing is acoustic source separation and environmental noise cancellation[2][5]. Built to operate in adverse acoustic conditions, Tofu-1 isolates human speech from complex background clutter, including broadcast media audio, vehicular road rumble, weeping infants, and building intercoms[1][2]. Furthermore, the model executes computational reasoning and external database calls in parallel with continuous conversation; it bridges processing pauses naturally with organic speech rather than awkward dead air, ensuring it never confirms an action until backend transactions are validated[6][5].
Bland AI has limited initial access to regulated corporate environments, primarily across health systems, insurance claims departments, retail banking centers, and municipal agencies[1][3]. Industry analysts observe that native speech-to-speech voice models are poised to overhaul enterprise customer service infrastructure, driving labor displacement in basic triage and contact center operations while simultaneously setting new baselines for consumer expectations in automated voice transactions[1][3].
- Bland AI
- Tofu-1
- Speech-to-Speech
Story 14 of 16
2 min read
miHoYo's 'Gamer' Model Navigates 3D Worlds Like a Human Player
Game developer miHoYo has unveiled 'Gamer,' a generalist Vision-Language-Action (VLA) foundation model designed for autonomous navigation and task completion in complex 3D gaming environments. Unlike traditional AI bots, Gamer processes raw video frames and generates real-time keyboard and mouse controls, mimicking human player interaction. It was trained on extensive gameplay data and utilizes advanced techniques to maintain long-term coherence in decision-making.
Read the full storyFold the full story1 min · 4 sources
Game development studio miHoYo’s Honkai AI R&D team unveiled "Gamer," a generalist Vision-Language-Action (VLA) foundation model engineered to autonomously navigate and solve complex, long-horizon tasks across rich 3D gaming environments[1][2]. Authored by a research collective including Run Luo, Kuan Zhang, Qi Deng, Yukun Chen, Yinhe Zheng, Xiaobo Xia, Dawei Jiang, and Shaoqing Ren, the model represents a departure from traditional reinforcement-learning bots[2][3]. Instead of querying direct memory variables or proprietary engine API endpoints, Gamer operates end-to-end like a human player - consuming raw video frames as visual input and generating real-time mouse and keyboard control trajectories[1][2].
Modern 3D open-world titles present challenges that mirror real-world robotics: severe partial observability, spatial navigation across irregular 3D topography, deferred reward schedules, and multi-stage causal reasoning[2]. Standard vision-language models frequently struggle when transitioning from static visual question-answering to interactive, low-latency control loops[2]. To bridge this gap, miHoYo trained Gamer through massive Continual Pre-Training (CPT) on multi-modal human gameplay streams, supplemented by sparse reasoning modules that deliberate over high-level quest objectives while maintaining sub-second motor reflexes[1].
The architecture integrates Trajectory-Aware Group Relative Policy Optimization (TA-GRPO) to align the agent’s sequential decision-making over prolonged questlines, minimizing catastrophic drifting over hundreds of consecutive actions[1]. To achieve practical operational throughput, the system executes on a streaming inference pipeline powered by an optimized vLLM serving stack, allowing the model to interpret visual feeds and stream precise control commands without frame stutter[1].
By treating high-fidelity commercial video games as rigorous, reproducible proxies for embodied real-world environments, Gamer positions video games as a crucible for generalist agentic intelligence[2]. The breakthrough demonstrates that the vision-language-action paradigms currently emerging in physical robotics can be accelerated inside complex 3D synthetic simulations, providing a template for agents that manipulate complex digital tools, simulate player behavior, and autonomously stress-test expansive software systems without bespoke scripting[2][4].
- miHoYo
- Gamer
- Vision-Language-Action
Story 15 of 16
2 min read
HerAgent Harness Solves Coding Agent Runtime Failures with Checkpointing
A new system called 'HerAgent' has been introduced to tackle a major issue in autonomous coding: runtime environment setup failures. Researchers identified that establishing correct build tooling, package dependencies, and runtimes is the primary obstacle for AI coding agents in real-world scenarios. HerAgent employs block-level checkpointing within Docker containers to create atomic snapshots, allowing for rollback to previous stable states when errors occur, thereby improving reliability and reducing resource consumption.
Read the full storyFold the full story1 min · 2 sources
Addressing one of the most pervasive failure modes in autonomous software engineering, researchers from University College London, Uppsala University, and Carnegie Mellon University unveiled "HerAgent"[1]. The investigation, authored by Xiang Li, Siyu Lu, Federica Sarro, Claire Le Goues, and He Ye, identifies runtime environment setup as the dominant operational failure point for autonomous coding systems[1][1]. While frontier models have achieved high scores on synthetic code-generation benchmarks, deploying these models in real-world repositories routinely breaks down when establishing the underlying build tooling, resolving native language runtimes, and harmonizing package dependencies[1][2].
Environment setup is stateful, extended-horizon, and vulnerable to cascading, silent side effects[1]. A single misconfigured system package or broken library can subtly pollute a system image, causing downstream patch validations and regression test suites to fail without generating an informative diagnostic error[1]. Existing autonomous coding harnesses typically alternate between two flawed approaches: single-command trial-and-error (which frequently pollutes the container environment beyond repair) or monolithic script re-generation (which repeats expensive compilation loops and rapidly exhausts LLM token budgets)[1].
HerAgent resolves this through a block-level checkpointing harness integrated on top of the Docker Engine[1][1]. The framework structures environment provisioning into semantic, modular command blocks (such as system dependency installation, compiler toolchain setup, and package resolution)[1]. At each block boundary, the harness commits an atomic container layer snapshot[1]. If a failure emerges during command execution, the agent initiates a two-tier recovery protocol: it first attempts localized, in-place repairs within the active block; if the failure persists or corrupts system invariants, the harness immediately rolls the container state back to the validated prefix snapshot without discarding previously established stages[1].
In systematic evaluations against challenging benchmarks, including SetupBench, HerAgent achieved environment configuration success rates of up to 90.7% while slashing token consumption and compute overhead by up to 94.5% compared to existing baselines[1][1]. The methodology shifts autonomous coding architecture away from pure prompt optimization toward systems-level state virtualization, providing enterprise engineering teams with an automated harness to reproduce legacy bugs, execute regression checks, and run computational science pipelines reliably[1][1].
- HerAgent
- autonomous coding
- runtime environment
Story 16 of 16
2 min read
South Korea Faces Exam Integrity Crisis Amid AI Cheating Scandal
South Korea is confronting an educational integrity crisis following a candidate's confession to using generative AI for cheating on a national certification exam. The incident has raised serious concerns about the security of the upcoming CSAT, the country's crucial college entrance exam. Authorities are grappling with how to detect advanced AI hardware and potential fraud that could undermine the meritocratic system.
Read the full storyFold the full story1 min · 7 sources
South Korea's educational authorities faced emergency parliamentary scrutiny after a candidate admitted to executing an AI-assisted cheating operation on a national certification exam, prompting fears regarding the integrity of the forthcoming College Scholastic Ability Test (CSAT), known locally as the Suneung[1][2][3]. The incident erupted after 34-year-old Han Won-seok confessed via an online video that he achieved top marks on the national tax accountant exam by using micro-cameras to transmit test questions to an external generative AI engine, receiving real-time solutions on a concealed handset[1][4].
The revelation triggered an emergency legislative session of the National Assembly's Education Committee in Seoul[4][5]. Lawmakers raised alarms over the security of the Suneung, the country's college admissions exam taken by more than 500,000 students[1][6]. In a society where university placement heavily dictates corporate recruitment, socioeconomic trajectory, and professional mobility, the editorial boards of major national publications, including the Hankyoreh, warned that unmonitored multimodal generative AI devices could undermine the foundational credibility of the national meritocracy[6][7].
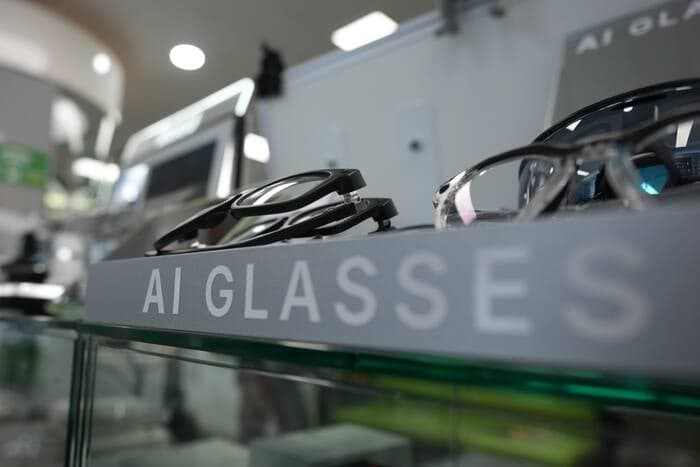
Testimony before lawmakers focused on the challenges of detecting modern miniaturized generative AI hardware[1][5]. Education Minister Choi Kyo-jin resisted proposals from certain lawmakers to postpone the national examination, insisting that delays would inflict disproportionate collateral disruption on students[7]. However, education officials conceded that standard radio-frequency scanners and metal detectors are largely inadequate for identifying modern low-power micro-transmitters and smart glasses featuring integrated displays and horn-rimmed frames[1][7].
The crisis has spurred South Korean regulatory bodies to weigh unprecedented legislative and administrative remedies[1]. Authorities are evaluating proposals to mandate hardware-level fail-safes requiring all commercial AI wearable optics to emit unalterable acoustic signals or flashing visual LEDs during active image processing and data transmission[1]. Education policy specialists emphasize that the incident reflects a widening global crisis: as vision-capable generative models achieve immediate problem-solving competence, static, high-stakes written standardized testing models are becoming structurally vulnerable to discreet, real-time algorithmic fraud[1][3].
- South Korea
- Generative AI
- Exam Integrity
You're all caught up.
That's every story in Monday's PiBrief Tech. The next edition is already in the works.
Subscribe to receive daily briefings about AI and tech in your email.
Get PiBrief Tech in your inbox
A free newsletter on AI and technology, curated by senior software engineers at Big Tech. Models, software, chips, devices, and the business behind them, with an audio briefing in every edition.
Free forever / no account / 1-click unsubscribe